sep 2026 — present · ongoing
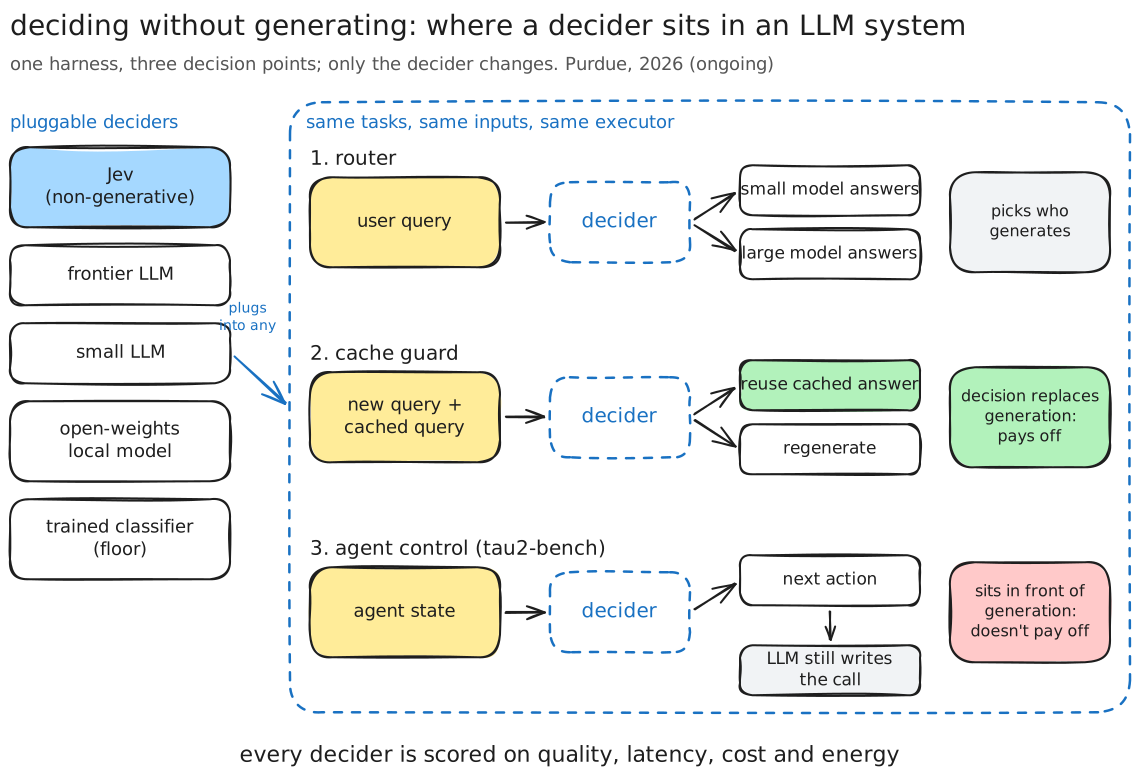
Deciding Without Generating: Jev at the Decision Points of LLM Systems
non-generative deciders vs llms where an llm system decides rather than writes
- llm agents
- τ²-bench
- benchmarking
- routing
- semantic caching
- energy
I am interested in how we know whether software systems actually work and what they actually cost: learned models for software analysis (bug finding, code classification, test generation), the efficiency of LLM and agentic systems, and the empirical side that makes both assessable: ground truth, benchmarks, and honest evaluation of what these tools do in real deployments.
non-generative deciders vs llms where an llm system decides rather than writes
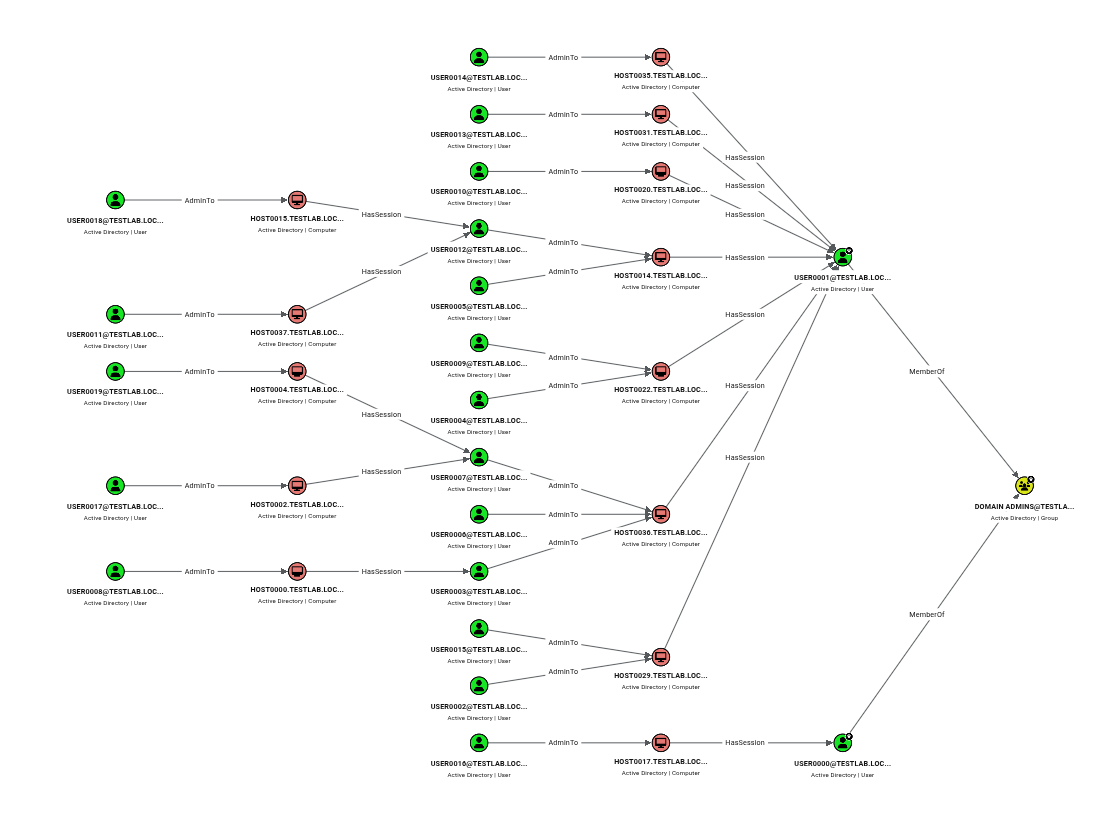
how far an adversary can quietly degrade the data bloodhound reasons over
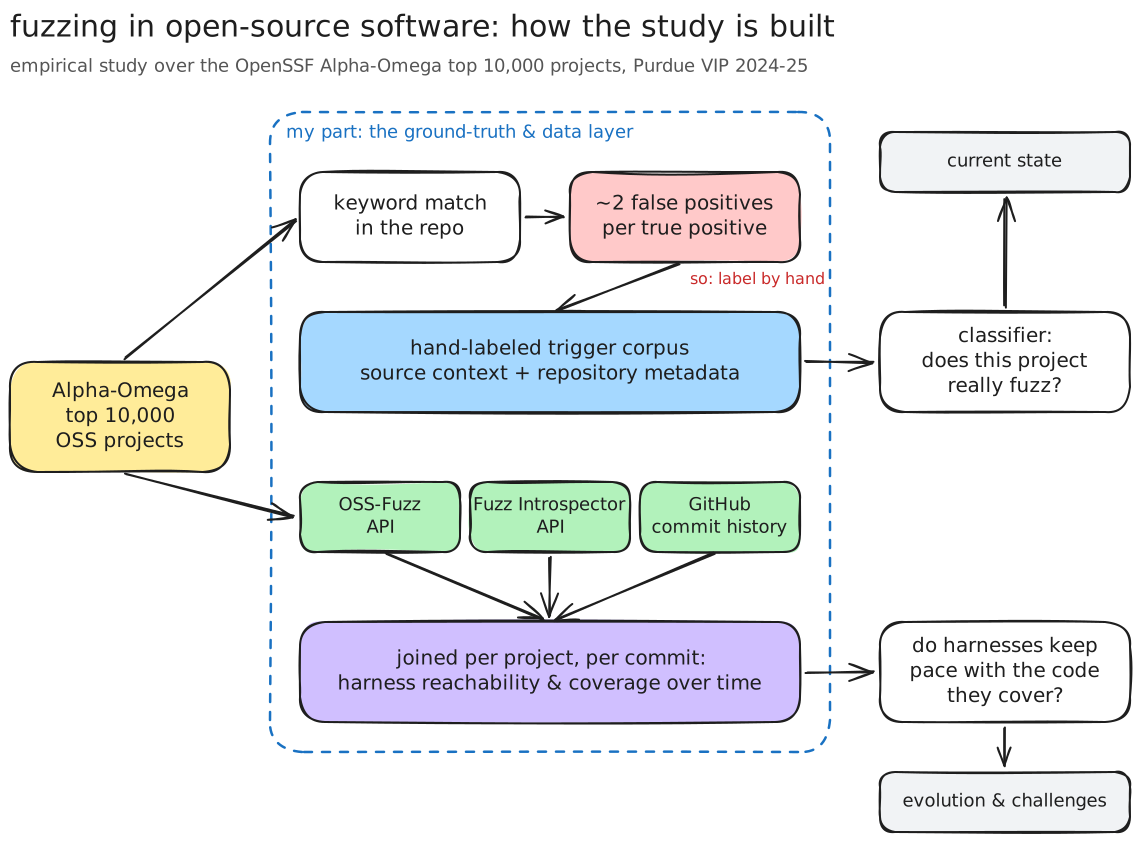
an empirical study of fuzzing practice across the top 10,000 oss projects