Deciding Without Generating: Jev at the Decision Points of LLM Systems
with Ahmed Elmersawy · Purdue University
ongoing
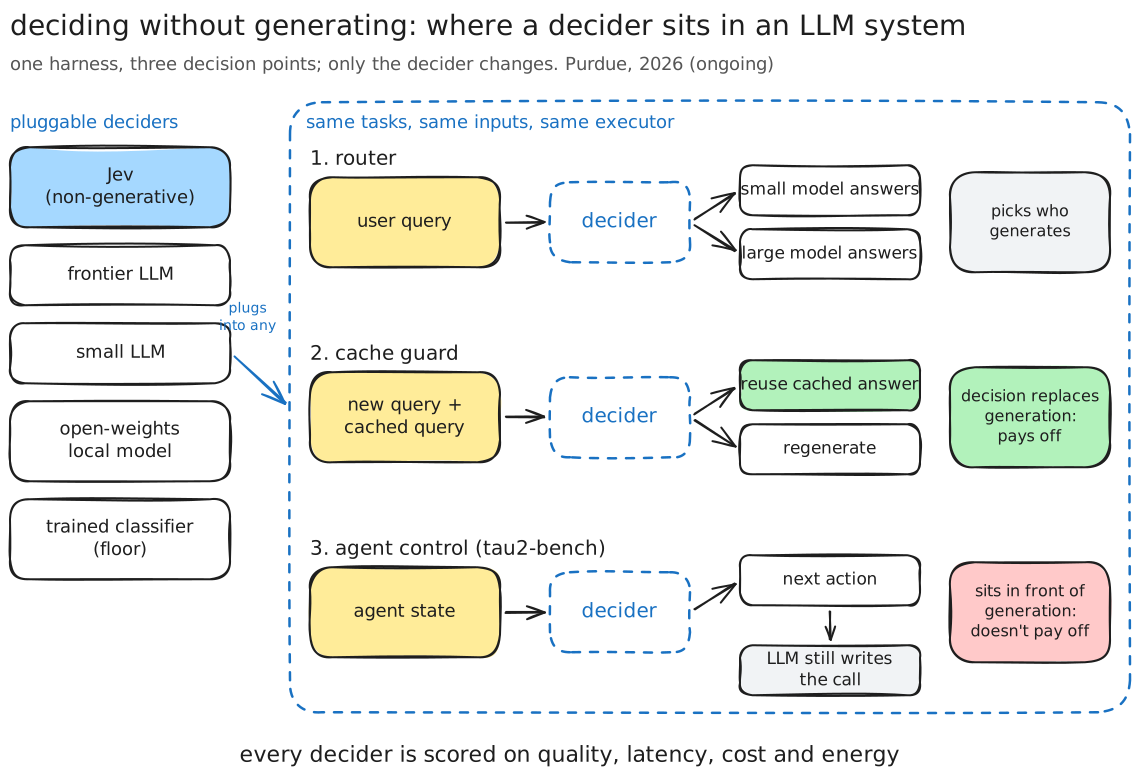
An efficiency benchmark of non-generative decision models (TypeSafe’s Jev) against LLMs at the points where an LLM system decides rather than writes: routing a query, reusing a cached answer, and controlling an agent. Every decider is scored on quality, latency, cost and energy.
Designed one harness in which any decider plugs into any decision point, starting with agent control on τ²-bench: same tasks, user simulator and executor, varying only the decider (Jev, frontier and small LLMs, an open-weights local model).
Built a decision-only replay benchmark: every decider answers identical saved agent states at least five times, scored with cluster-bootstrap confidence intervals.
Found that reference-agent labels score valid alternative actions as errors, so single-reference accuracy understates every decider.
Found that a separate decider pays off where its decision replaces generation (cache reuse), not where it sits in front of generation that happens anyway (agent control).
- llm agents
- τ²-bench
- benchmarking
- routing
- semantic caching
- energy